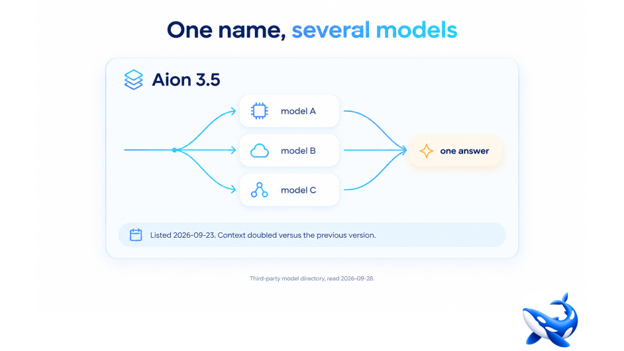
Every comparison table has a hidden assumption at the top: that one row is one model. The newest AI model added to the directory on 23 September 2026 does not satisfy it. Aion 3.5 is a collaborative system — a name you call that decides which underlying model answers, and sometimes combines more than one — and the difference between that and a single set of weights is not a detail. It decides what a per-token price means, what a context window means, and whether the score on a leaderboard is a property of the thing you are calling. On OrcaRouter each newest ai model row is an endpoint with a price attached, which is exactly the shape that makes an orchestrated entry look deceptively familiar.
What changed in this version
The headline in the vendor’s own framing is a doubled context window at the same price as the previous version. Read as a spec-sheet diff, that is a clean improvement: twice the working room, no increase in rate.
Read as a system, it needs a second question. Doubling the context of an orchestrator is not the same as doubling the context of a model. If the orchestrator holds the conversation and dispatches turns to a back-end, its context is the shared workspace; the back-end’s own limit is a separate constraint. Two systems can advertise the same window and behave completely differently as soon as a single turn exceeds whatever the sub-model can take.
That is a question the release material does not answer, and it is the first one to ask.
Why roleplay workloads expose the design
The vendor positions this family around collaborative roleplay and multi-character interaction, and that is a workload where orchestration stops being an implementation detail.
Consider what a long roleplay session actually requires. Distinct characters have to stay distinct across hundreds of turns — the same voice, the same knowledge, the same relationships. A single model doing this is fighting its own tendency to blend voices as the context fills. A system can split the problem: one pass handles character A, another handles character B, a third reconciles them into a scene. That is a genuinely different architecture, and on this workload it can beat a larger single model.
The cost of that design is that behaviour under load becomes a routing question. Which back-end answers a given turn may depend on the turn’s content, on what is available, or on a policy that is not published. Which means the model’s worst case is not its average case, and the variance you observe may come from routing rather than from sampling.
What the price actually prices
This is where an orchestrated entry breaks the arithmetic everyone brings to a price list.
For a single model, a per-token rate times a token count is a bill. For a system, one visible request can become several internal ones, and the tokens you are charged for may not be the tokens any one model produced. A per-token rate therefore describes the outer interface, not the computation.
That is not a scam; it is simply a different unit. The honest way to compare an orchestrated system against a single model is cost per completed session — the whole interaction, start to finish, including whatever internal work it took. And that comparison has to be run on your own transcript lengths, because the ratio between visible and internal tokens depends entirely on how the system decides to divide the task.
The measurements that do not transfer
There is no independent intelligence index page for this entry as of 28 September 2026, which we checked ourselves. That absence is worth more attention than it usually gets, because it is the same absence that a system creates for every benchmark.
A leaderboard score assumes a fixed function: same input, same model, same output distribution. An orchestrator with a routing policy is not a fixed function in the same sense — two runs of the same prompt can take different internal paths. Benchmarks can still be run, and their results are still meaningful as an upper bound on what the system can produce, but they measure the best path the router chose rather than the behaviour of a stable artifact.
The practical consequence: when you evaluate something like this, run each prompt several times and look at the spread. For a single model the spread tells you about sampling temperature. For a system it tells you about routing, which is a much larger effect and one you cannot tune away.
How to decide whether the architecture matters to you
Three questions, and they are separable.
Does your workload need character or persona consistency over long sessions? If yes, orchestration is a feature you are buying and the doubled context is the second-most interesting thing on the page. If no, you may be paying for a routing layer you never use.
Do you need reproducible outputs? A system with an unpublished routing policy is harder to reproduce than a single model, and if your product requires a defensible audit trail for a given answer, that is a real constraint rather than a philosophical one.
Is your cost model per-token or per-task? If you have built cost reporting on token counts, an entry like this will fit the report and mislead the reader. Per-task measurement is the only unit that survives contact with an orchestrator.
The wider pattern in this month’s releases
Two things can wear the same label in a model directory: a set of weights, and a system that selects among sets of weights. This month’s batch contains both, plus a third shape — a serving tier of an existing model sold under a new name. All three arrive as a row with a date and a price, and all three need a different question asked of them.
The habit worth keeping is to ask what the name refers to before asking how good it is. A name that resolves to weights can be compared on scores. A name that resolves to a serving configuration can be compared on price per token and latency. A name that resolves to a system can only be compared on the completed task, and any table that ranks it against single models is answering a question nobody asked.
Sourcing note: Aion 3.5’s listing date of 23 September 2026 and the doubling of its context window at an unchanged price are from a third-party public model directory read on 28 September 2026 and from the vendor’s own description of the version. The characterization of the family as a collaborative, multi-model system positioned around roleplay is the vendor’s own framing and is not an independent measurement. The absence of an independent intelligence index page for this entry was our own check on 28 September 2026, as was the statement that this model is not in OrcaRouter’s catalogue. No price, parameter count or index score is quoted because none is published; no figure has been estimated. The arguments about routing variance, the visible-versus-internal token ratio, and the per-task comparison are editorial framing rather than measured results. This article names no competing platform and describes none.